Scenario
Delay in receiving the Sensor alerts on the Manager
Applicable to Sensor models: NS-series and Virtual IPS Sensors
Sensor software versions: 10.1, 11.1
Problem type to be solved
Delay in the Sensor alerts being sent to the Manager
Sensor alerts are not seen in real time on the Manager
Time lag in sending the Sensor alerts to the Manager
Data/Information Collection
Steps:
Execute the following commands on the Sensor :
status(Execute 5 times in 10 seconds duration.)show sensor-load(Execute 5 times in 10 seconds duration.)getccstats(Enter debug mode and execute this command 5 times in 10 seconds duration.)Note
Also execute the same commands on a similar model Sensor, which does not have the issue.
Collect graphs for Sensor throughput utilization and port utilization.
Collect the attack csv file for this Sensor from the Attack Log page.
Collect the alert archival for the last 24 hour time duration.
Retrieve the configuration backup of the Manager.
Create/collect the network diagram that clearly indicates where the Sensor and the Manager are located.
Troubleshooting steps
Check if there are any network connectivity issues or any delay in the network. If there is a delay in the network between the Sensor and the Manager, it can lead to low alert rates.
Verify that the entire link between the Sensor management port and the Manager is 1G auto, and they are using the correct CAT6 cables.
Check if the other Sensors connected to the same Manager are also facing this issue. If yes, it is a Manager issue.
Check the Sensor policy being used. If the Default Testing or Default Exclude Informational is used, the Sensor processes more alerts and alert generation rate increases. Switching to Default Prevention policy can help resolve the delay issue sometimes.
Check if there are any saved alerts/packetlogs on the Sensor.
Command:
show savedalertinfoCheck if there is any specific category of alerts, which is delayed or all the alerts are delayed. Also check if the system events that are being raised, are also delayed.
Check if the alerts are seen in the Attack Log page as the alerts are restored here from the database. This check will confirm if the issue is on the database or cache. Check the database size and if it is very high, purge and tune the database.
Check the time on the Sensor and whether it matches with the Manager system time. If there is any issue with the time stamp, the Manager may show the wrong timestamp in the Attack Log page, which can incorrectly appear as alerts being delayed.
Check the rate of alert generated/detected by the Sensor using the following command in debug mode:
getccstatsThe command displays the following statistics:
The status of trust between the Manager and Sensor, Sensor installation, alert channel, peer alert channel, etc.
The alert suppression/throttling configuration status and suppression intervals
The sensor failover action (1 = Enabled, 2 = Disabled) and failover status (1 = Active, 2 = Standby, 3 = Init/Not Applicable), failover peer status (1 = Up, 2 = Down, 3 = Incompatible, 4 = Compatible, 5 = Init/Not Applicable), fail-open status (1 = Enabled, 2 = Disabled)
The count of detected alerts (signature-based, scan/recon, DoS) sent to management port and peer Manager (in case of MDR)
The count of throttled alerts
The count of alerts sent to and received from Correlation Engine and alert correlation counts
The count of alerts in ring buffer, queued to be sent to the Manager
The ACL alerts’ throttling configuration status (throttling interval and threshold)
The count of throttled ACL alerts (IPS)
The Sensor reboot count and/or alert wrap count
For example, consider the following statistics from
getccstatscommand that indicate that many alerts are still pending in ring buffer:AlertsInRngBufPriCount = 83621AlertsInRngBufSecCount = 83606PutAlertInRngBufErrCount = 6499317The alert rate could be so high that the Manager may not be able to handle. Subsequently, it introduces a delay that is similar to backoff (with the delay reaching a max of 30 seconds per alert) and this causes the alerts to be queued up in ring buffer. Once this condition is reached, the alerts delay will increase with time. To recover, check the type of attacks and then try to create an exception rule to filter the attack, and see if the Manager recovers.
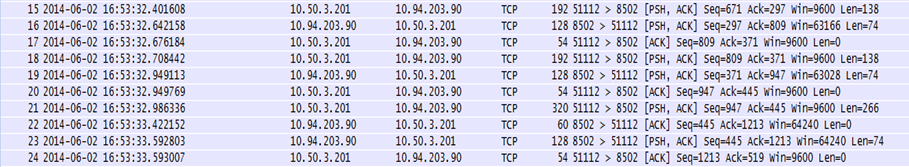
Collect the packet captures at the Sensor and the Manager side to identify whether the issue is at the Sensor/Manager side or network side.
On the Manager, use Wireshark or equivalent to collect packet captures on the Manager port 8502.
Sample packet capture on the Sensor:
Sample packet capture on the Manager:
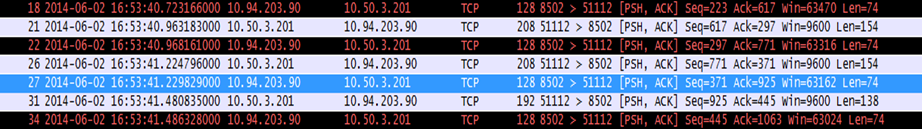
Using packet captures from the Sensor and the Manager, which are taken simultaneously, you can identify if there is a delay in the Sensor sending the alert to the Manager, or there is a delay in the Manager sending the alert acknowledgment to the Sensor, or both are happening which indicate a potential network issue.
Check if Layer 7 Data Collection is enabled on the Sensor. There is a known issue when Layer 7 Data Collection is enabled, where the alerts in the Attack Log page are no longer received in real time.
IntruDbg#> show l7dcap-usageLayer-7 Dcap Buffers Allocated at Init 16000Layer-7 Dcap Buffers Available now 16000Layer-7 Dcap Buffers Alloc Errors 0Layer-7 Dcap Alert Buffers Allocated 40960Layer-7 Dcap Alert Buffers Available 40960Layer-7 Dcap Alert Buffers Allocate Error 0Layer-7 Dcap Regular Alert's Sent 0Layer-7 Dcap Special Alert's sent 0Layer-7 Dcap Context End Alert's Sent 0Layer-7 Dcap CB InActive when DCAP Called 0Layer-7 Dcap Ring Buffer Errors 0Alert Ring Buffer Full Cnt 0Num Alerts Dropped at Sensors 0Layer-7 Dcap Fifo Check Seen 0On the Manager database, use SQL queries output to check the frequency of alerts going to the Manager. This can be done by logging into MariaDB on the Manager server and executing the following command:
Get Sensor ID from database:
select sensor_id, name from iv_sensor;Input the time range for which the alert generation rate needs to be checked:
SELECT "2014-05-29 18:39:47", "2014-05-30 18:39:47" INTO @stdate, @enddate;Total Attacks for Sensor ID and the time range:
SELECT sensorid,COUNT(*) atcount FROM iv_alert WHERE creationtime BETWEEN @stdate AND @enddate GROUP BY sensorid ORDER BY atcount;Total packetlog for Sensor ID and time range:
SELECT sensorid,COUNT(*) pktcount FROM iv_packetlog WHERE (creationtime BETWEEN @stdate AND @enddate) AND sensorid=<id of problematic sensor> GROUP BY sensorid ORDER BY pktcount;
If the problem still persists, contact Trellix Support for further assistance.